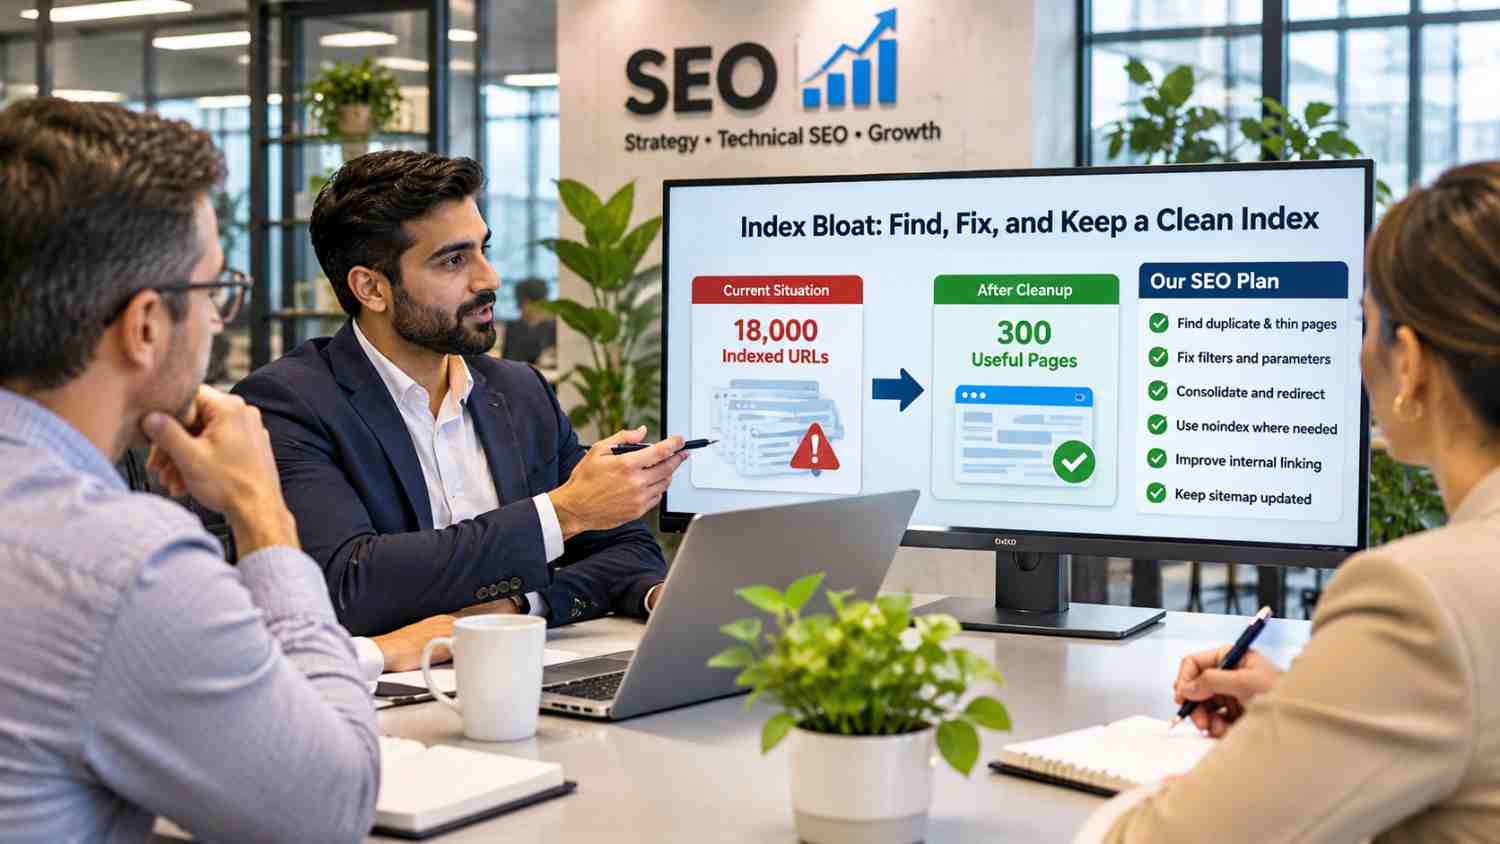
A small website has 300 useful pages but Google knows about 18,000 URLs.
Most of the extra URLs are not hacked pages. They are filter combinations, tracking parameters, old tags, search results, print versions, duplicate product URLs, and empty archive pages. The site owner sees a large number in a crawl report and thinks, “Google must hate this website.”
Usually, the situation is less dramatic. But it still deserves attention.
Index bloat is the loose SEO term for a search index filled with pages that do not deserve to appear in search. Some are duplicates. Some are too thin to help anyone. Some are old and no longer relevant. Others exist only because the website creates a new URL every time a visitor sorts or filters a page.
The fix is not to remove pages at random. First find out what Google can crawl, what it has indexed, and which URLs are actually useful.
What Index Bloat Means
Index bloat is not an official Google error label. It is a way SEO teams describe an oversized or messy URL inventory.
A Large Index Is Not Automatically A Problem
A large ecommerce store may have hundreds of thousands of valid product and category pages. A news website may publish thousands of articles each year. Those numbers are not bloat if the pages are useful, distinct, crawlable, and intended for search.
The problem is the gap between useful pages and unnecessary URLs.
A website with 2,000 products and 60,000 filter URLs may have a URL management problem. A website with 20,000 carefully written local pages may not.
Google’s crawl budget guidance says smaller sites that are crawled promptly usually do not need advanced crawl-budget work. The guidance is mainly aimed at very large or frequently changing sites.
That is worth saying because “crawl budget” gets blamed for everything. A 40-page brochure site does not need a six-month crawl-budget project.
What Bloat Can Look Like
Common examples include:
Several URLs showing the same page
Faceted filter and sort combinations
Internal search result pages
Old products and expired listings
Thin tag or author archives
Duplicate print or mobile URLs
Session IDs and tracking parameters
Empty category pages
Staging or test pages exposed to crawlers
Soft 404 pages that return a normal 200 response
Each case needs a different response. That is why one global rule can make the problem worse.
Why Index Bloat Matters
Google does not promise to crawl every URL it knows about. Crawlers have limited time and resources, and they try to decide which URLs deserve attention.
Crawlers May Spend Time On The Wrong URLs
Google says duplicate URLs can waste crawling time that could have been used on unique pages. Its guidance recommends managing the URL inventory, consolidating duplicates, keeping sitemaps current, and returning proper 404 or 410 responses for permanently removed pages.
This matters most when a site is large, changes often, or has many URLs classified as discovered but not indexed. On a small site, the larger issue may simply be confusing reports, weak internal linking, or a poor user experience.
For smaller sites, a focused technical SEO service is usually more useful than a dramatic promise to “fix crawl budget” overnight.
Search Signals Can Be Split
If the same product is accessible at five URLs, external links and engagement signals may be spread across those versions. A canonical URL can help Google understand which version you prefer.
Google says redirects are a strong canonical signal, rel="canonical" is also a strong signal, and sitemap inclusion is a weaker signal. These signals work best when they agree.
A canonical tag is not a magic eraser. Google may choose a different canonical if the page signals conflict or the pages are not genuinely similar.
Search Results Can Fill With Weak Pages
Thin pages can make a site look less useful when they enter search results. A page with two copied sentences, no products, and no clear purpose is not helping visitors.
Still, do not confuse “not currently indexed” with “bad.” Google may choose not to index a useful page because it has limited demand, is new, or is one of many similar pages. The goal is not to force every URL into the index. The goal is to keep the important pages clear and accessible.
How To Find Index Bloat
Start with evidence, not a plugin score.
Check Search Console First
Open the Page Indexing report in Google Search Console. Look for patterns such as:
Duplicate without user-selected canonical
Google chose a different canonical
Crawled, currently not indexed
Discovered, currently not indexed
Soft 404
Excluded by noindex tag
Blocked by robots.txt
These labels do not all mean the same thing. “Crawled, currently not indexed” is not proof of a technical failure. It means Google crawled the URL but did not include it at that time.
Export examples from each group. One URL tells you very little. Twenty URLs with the same parameter pattern usually tell you where to look.
Compare Sitemaps With The Live Site
Your XML sitemap should contain the canonical URLs you want Google to discover and understand. It should not be a dumping ground for every URL the CMS has created.
Compare the sitemap with:
URLs found in a crawl
URLs receiving organic visits
URLs linked from important pages
URLs returning 200 status codes
URLs Google has indexed
If the sitemap lists old product URLs, filtered pages, or redirected addresses, clean it up. Google describes sitemaps as a weaker canonical signal, but a clean sitemap still gives the crawler a clearer inventory.
Crawl The Website And Group URL Patterns
Use a crawler to collect URL, status code, title, canonical, robots directive, word count, links, and indexability data. Then group URLs by pattern rather than reviewing them one at a time.
Look for patterns such as:
?sort=
?filter=
?page=
?utm_
/tag/
/author/
/search/
/print/
Old product or category folders
A technical SEO audit can help find these patterns, but the important step is deciding what each URL is for. A crawl report can show duplication. It cannot decide whether a filtered page is valuable to customers.
Decide Which URLs Deserve To Stay
Before fixing anything, place each URL group into a simple category.
Keep And Improve
Keep pages that have a clear purpose, useful content, demand, links, conversions, or a role in the customer journey.
An underperforming product page may need better information. It does not need a noindex tag just because it has few visits this month.
Consolidate
Consolidate pages when several URLs represent the same content and one version should remain visible.
Use a permanent redirect when an old URL should send users and crawlers to a replacement. Use a canonical tag when duplicate or very similar versions need to point to a preferred URL but should remain accessible.
Link internally to the preferred URL. Do not send your own visitors through tracking or duplicate versions when you can avoid it.
Remove
Remove pages that have no useful replacement and no reason to exist. Return a 404 or 410 status for permanently removed content. Google says these status codes are clearer signals than leaving dead pages live with a soft 404.
Do not redirect every deleted URL to the homepage. A homepage is not a relevant replacement for an expired blog post or discontinued product.
Keep Accessible But Out Of Search
Some pages help users but should not appear as search results. Examples may include internal search pages, account areas, cart pages, or certain filtered views.
Use a noindex directive when the page must remain crawlable but should not appear in Google Search. Google’s documentation says noindex must be visible to Googlebot. A URL blocked in robots.txt cannot be crawled, so Google may not see the noindex instruction.
Choose The Right Fix
This is where many index-bloat clean-ups go wrong. The tools sound similar, but they do different jobs.
Canonical Tags For Duplicate Versions
Use rel="canonical" when multiple pages are duplicate or very similar and you want one preferred version.
Example: a product page is available with a tracking parameter, but the clean product URL is the version you want in search.
Canonical tags are hints, not commands. Keep the content genuinely similar, use an absolute URL, and make your internal links and sitemap support the same preferred address.
Google does not recommend using noindex to select a canonical page within a duplicate set. It says canonical is the preferred solution when the goal is consolidation.
Redirects For Retired URLs
Use a permanent redirect when an old URL has a clear replacement. This passes users to the new location and gives Google a strong signal about the preferred URL.
Check redirect chains. Old URL to temporary URL to category page to homepage is not a clean migration. Redirect directly to the closest relevant replacement.
Noindex For Useful But Non-Search Pages
Use noindex for pages that should stay available on the site but do not need search visibility. Keep the page crawlable long enough for Googlebot to read the directive.
After adding it, check the rendered HTML and Search Console. A template can accidentally place noindex on important pages or omit it from a filtered page type.
Robots.txt For Crawl Control
Use robots.txt to stop crawling URLs that do not need to be fetched, especially large sets of faceted navigation URLs that create little search value.
Do not use robots.txt as a canonical tool. Google may still know about a blocked URL and potentially index it without seeing the page content. Google’s canonical documentation specifically warns against using robots.txt for canonicalization.
Google’s faceted navigation guidance says parameter-based filters can create an almost unlimited URL space. If those URLs do not need to appear in search, disallowing the pattern or using URL fragments can reduce crawling.
Fix Common Causes Of Bloat
Faceted Navigation
Filters for colour, size, price, location, and sorting can create thousands of combinations.
Decide which combinations deserve their own search-friendly landing pages. Build those pages deliberately. For the rest, prevent crawling or keep them out of search using an approach that fits the site.
Do not block every filter automatically. A “red running shoes” page may be useful, while a URL combining five filters and sorting options may not be.
Internal Search Results
Internal search pages often contain changing results, thin text, and little standalone value. They can also create endless URLs from misspellings and random queries.
In most cases, keep internal search results out of the index. Make sure your site navigation and category pages still help users find important content.
Tag And Archive Pages
A tag page with dozens of relevant articles can be useful. A tag page with one post and a generic title is usually not.
Review archive templates in groups. Improve the useful ones with clear descriptions and links. Noindex or remove empty and weak archives.
Old Products And Listings
A discontinued product may deserve a replacement page, a related product redirect, or a short explanation for customers. A property listing that is permanently gone should not sit online with a “call us for details” message.
Return the right status and update internal links. Do not leave expired pages live just because deleting them feels uncomfortable.
Soft 404 Pages
A soft 404 looks like a normal page to the server but tells the visitor that nothing is really there. Google notes that soft 404 pages can continue to be crawled and waste resources.
Return a real 404 or 410 for pages with no replacement. Give users helpful navigation, but do not disguise a missing page as a successful one.
What Not To Do
Do not noindex half the website to make the indexed URL count look smaller. Do not block URLs before checking whether Google needs to see a noindex tag. Do not canonicalise different topics to one page just because the pages have low traffic.
Also, do not obsess over an arbitrary index-to-page ratio. There is no universal “healthy” number. A shop with variants, regional pages, and editorial content will have a different URL profile from a five-page service business.
The right question is: are search engines spending time on pages that help users, or on pages created accidentally by the website?
A Practical Cleanup Order
Work in this order:
Remove or redirect permanently retired pages.
Fix duplicate URL patterns and inconsistent canonicals.
Clean the sitemap so it contains preferred, indexable URLs.
Control faceted navigation and internal search URLs.
Review thin archives, tags, and location pages.
Improve important pages that are weak rather than hiding them.
Recheck Search Console after Google has recrawled the changes.
Make one logical change at a time when possible. If you block filters, change canonicals, delete thousands of pages, and redesign the site in the same week, diagnosis becomes difficult.
For a broader on-page SEO review, check that important pages have clear titles, useful content, logical internal links, and one preferred URL.
If the site is large or changes frequently, review its crawl budget alongside the index patterns. The two issues often overlap, but they are not identical.
Five FAQs About Index Bloat
1. Is index bloat a Google penalty?
No. Index bloat is an SEO description, not a named Google penalty. It can create crawling, reporting, duplication, and search-quality problems, especially on large or frequently updated sites. A messy index does not automatically mean Google has applied a manual action.
2. How do I know if my site has index bloat?
Compare your useful page inventory with Search Console’s Page Indexing report, sitemap URLs, and a technical crawl. Look for repeated parameter patterns, duplicate pages, thin archives, old URLs, soft 404s, and large groups of pages that have no search or user purpose.
3. Should I use noindex or robots.txt to remove low-value pages?
Use noindex when Google should crawl the page and see that it must stay out of Search. Use robots.txt when you need to reduce crawling of URL patterns that do not need to be fetched. Do not block a page in robots.txt if Google needs to read its noindex directive.
4. Does a canonical tag remove a page from Google’s index?
No. A canonical tag tells Google which similar URL you prefer. Google may choose a different canonical if its systems disagree. If the page must not appear in Search, use a visible noindex directive or remove the page, depending on the situation.
5. How long does it take to fix index bloat?
There is no fixed timetable. Google must recrawl the affected URLs and process the changes. Small corrections may appear quickly, while large sites with many blocked, duplicate, or old URLs can take much longer. Monitor patterns in Search Console instead of expecting the total to change overnight.
The Sensible Way To Fix Index Bloat
Index bloat is not solved by chasing the smallest possible indexed-page count. It is solved by giving every URL a clear job.
Keep useful pages. Improve weak pages with real value. Consolidate duplicates. Redirect genuine replacements. Remove dead content. Use noindex and robots.txt for the right reasons, not as interchangeable buttons.
Once the URL inventory is cleaner, Google can spend more of its attention on the pages you actually want found. That is the point of the work.