Don't block AI bots as one group. Sort them by job first. Keep search and answer crawlers open (Googlebot, Bingbot, OAI-SearchBot, Claude-SearchBot, PerplexityBot), decide separately on training crawlers (GPTBot, ClaudeBot, CCBot), and protect your heavy URLs like cart, checkout and internal search from every bot. Then rate limit anything that crawls too hard and check your CDN settings, because a single firewall toggle can undo a perfect robots.txt file.
What Is AI Bot Traffic?
AI bot traffic is any automated request to your website from a crawler or agent run by an AI company. These bots fall into three groups, and each one affects your site differently.
Bot type | What it does | Examples | Should you block it? |
|---|---|---|---|
Search crawlers | Index pages so AI tools can cite you in answers | OAI-SearchBot, Claude-SearchBot, PerplexityBot | No, if you want AI visibility |
Training crawlers | Collect content to train future AI models | GPTBot, ClaudeBot, CCBot | Your choice |
User agents | Fetch a page live when someone asks an AI tool a question | ChatGPT-User, Claude-User, Perplexity-User | Usually no |
The problem starts when site owners see a spike in bot traffic, panic, and block "AI" with one rule. That one rule often removes them from ChatGPT search, Perplexity and Claude answers at the same time.
Who Needs to Manage AI Bot Traffic?
You need an AI bot policy if your site shows any of these signs:
Server slowdowns or hosting overage bills with no matching rise in human visitors
Unknown bots hitting cart, filter or search URLs thousands of times a day
A robots.txt file nobody has reviewed since 2023
Strong Google rankings but zero mentions in ChatGPT or Perplexity
E-commerce stores, publishers, SaaS companies and local service businesses feel this most. Small brochure sites usually need only a clean robots.txt and a quick CDN check.
Which Crawlers Should You Never Block?
Never block Googlebot or Bingbot. Google's AI Overviews and AI Mode pull from the same index Googlebot builds, so blocking it removes you from both regular search and AI answers. Microsoft Copilot leans on Bingbot's index in the same way.
Keep these open too if AI visibility matters to you:
OAI-SearchBot: OpenAI says sites that opt out of it won't appear in ChatGPT search answers.
Claude-SearchBot: Indexes content for Claude's web search.
PerplexityBot: Powers Perplexity's cited answers.
ChatGPT-User and Claude-User: These fetch pages only when a real person asks.
One common mix-up: Google-Extended is not a crawler. It's a robots.txt token that tells Google not to use your content for Gemini training. Google states it doesn't affect your inclusion or ranking in Google Search, and that includes AI Overviews.
How to Manage AI Bot Traffic in 6 Steps
Step 1: Measure Before You Block
Look at your server logs or your CDN's bot analytics before you change anything. Find out which bots visit, how often, and which URLs they request. If you use Cloudflare, the AI Crawl Control panel shows this per bot. Without this data, you're guessing.
Step 2: Sort Every Bot by Purpose
Group each bot you find into search, training or user agent using the table above. Treat each company's bots as separate decisions. Blocking GPTBot doesn't have to mean blocking OAI-SearchBot, because OpenAI runs them as independent settings.
Step 3: Write a Split robots.txt File
Give search crawlers and training crawlers separate rules. Here's a starting template:
# Search and answer crawlers: keep public content open
User-agent: Googlebot
User-agent: Bingbot
User-agent: OAI-SearchBot
User-agent: Claude-SearchBot
User-agent: PerplexityBot
Allow: /
Disallow: /cart/
Disallow: /checkout/
Disallow: /search
# Training crawlers: block only if you don't want training use
User-agent: GPTBot
User-agent: ClaudeBot
User-agent: CCBot
User-agent: Google-Extended
User-agent: Applebot-Extended
Disallow: /
# All other bots
User-agent: *
Disallow: /cart/
Disallow: /checkout/
Disallow: /search
Sitemap: https://www.example.com/sitemap.xml
A bot follows only the group that names it most specifically, so repeat your private paths in every group. Also delete old tokens like anthropic-ai and Claude-Web. Anthropic has retired them, so those lines no longer do anything. OpenAI notes that search changes can take about 24 hours to apply.
Step 4: Protect Expensive URLs, Not Whole Bots
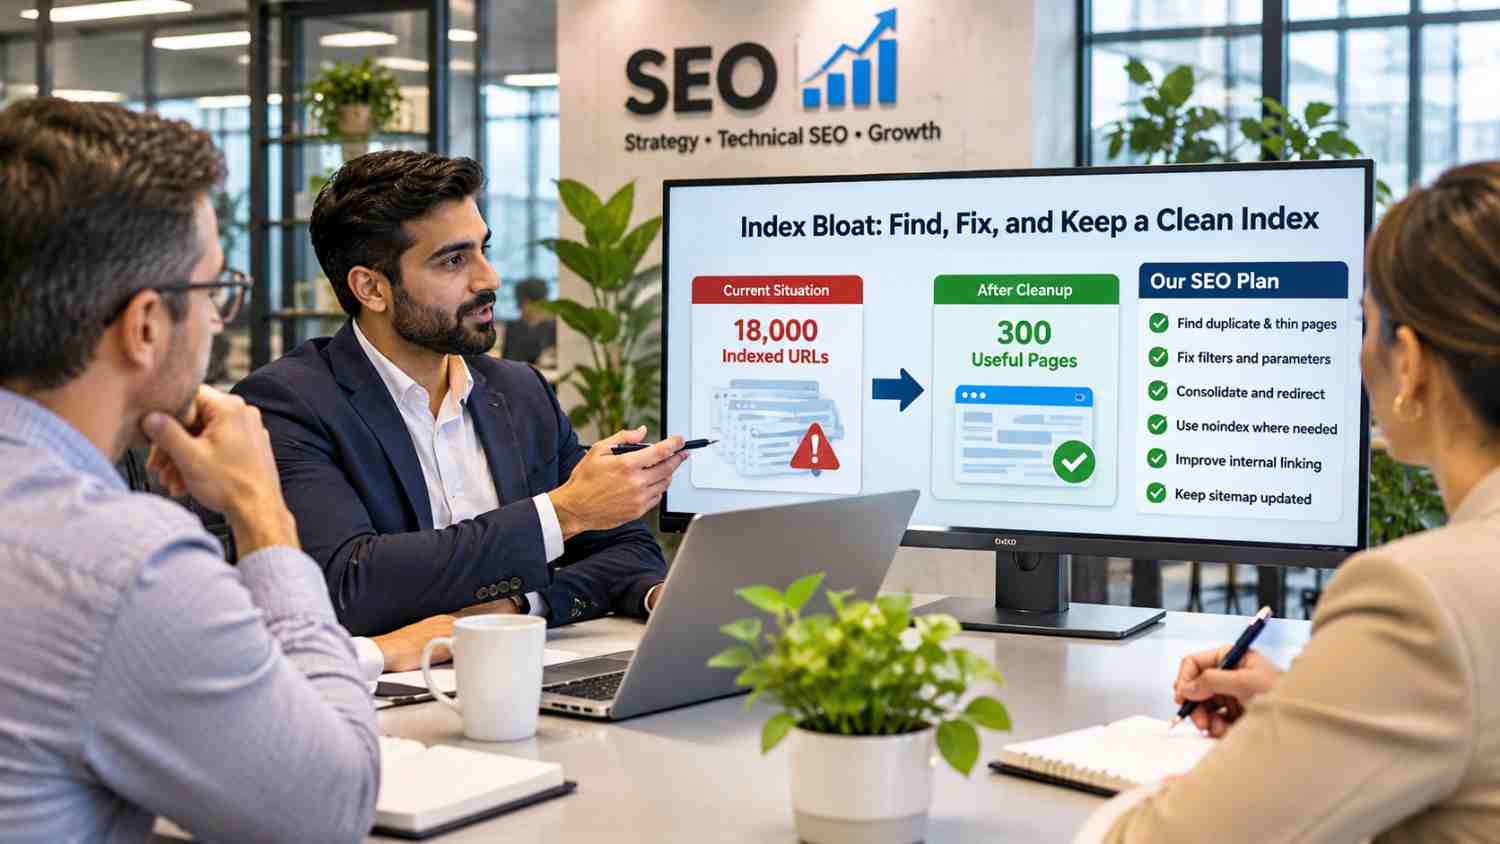
The real server drain usually comes from dynamic pages, not blog posts. Cart links, filtered product pages, internal search results and URLs with changing parameters force your server to build a fresh page on every hit. Kinsta recorded 7.67 million add-to-cart requests from bots in a single day across its network. Block those paths for all bots and leave your content pages open. This also helps your crawl budget and reduces index bloat from parameter URLs.
Step 5: Rate Limit and Verify at the Edge
Robots.txt is a request, not a lock. Bots can ignore it. For bots that crawl too hard, use rate limiting in your CDN or firewall instead of a full block, and return a 429 status code so polite crawlers slow down. Our guide to HTTP status codes explains why a 429 is safer than a 403 for real crawlers.
Also verify that "Googlebot" really is Googlebot. Run a reverse DNS lookup on the IP, confirm it ends in googlebot.com or google.com, then run a forward lookup to confirm it matches. OpenAI publishes IP lists for its bots too. Fake crawlers that fail these checks can be blocked safely.
Step 6: Check Your CDN and Hosting Defaults
Your firewall can block AI search bots even when robots.txt allows them. Cloudflare's defaults have changed several times since 2025. Its current setup splits AI traffic into Search, Agent and Training, and as of its November 2026 documentation, new domains start with all three set to Allow.
Here's the catch most guides miss: Cloudflare's Training policy also covers mixed-purpose crawlers that do both training and search. Set Training to Block and you may cut off a crawler that feeds AI search results. Open your dashboard, check each setting, and test after every change. Hosts like Kinsta also offer their own AI crawler toggles, so check those as well.
Common Mistakes That Hurt AI Visibility
Blocking every AI bot with one "block AI" switch
Blocking Google-Extended and expecting it to remove you from AI Overviews (it won't)
Leaving a staging Disallow: / rule on the live site
Trusting user-agent names without verifying IPs
Adding llms.txt and assuming it overrides robots.txt blocks (it doesn't)
How Smart Bot Management Protects Your Brand's AI Visibility
AI tools can only cite pages their search crawlers can reach. Every wrongly blocked search bot means fewer chances for ChatGPT, Perplexity or Claude to name your brand when customers ask for a recommendation. As AI agents start comparing and booking on users' behalf, open access to your service, pricing and contact pages matters even more.
After you update your rules, track the result. Watch AI referral traffic in your analytics and track brand mentions in AI search every month. If visits stay flat even though crawlers can reach you, run an AI search visibility audit to find the content gaps.
Need help setting this up? The Eyes On Solution technical SEO team audits robots.txt, CDN rules and server logs, and our GEO services help your brand get cited once AI crawlers can find you.
FAQs
Does blocking AI crawlers hurt my SEO?
Blocking training crawlers like GPTBot, ClaudeBot or Google-Extended doesn't affect your Google or Bing rankings. Blocking Googlebot, Bingbot or AI search crawlers like OAI-SearchBot does hurt you, because it removes you from search results or AI answers.
What is the difference between GPTBot and OAI-SearchBot?
GPTBot collects content for training OpenAI's models. OAI-SearchBot indexes pages so ChatGPT search can show and cite them. You can block GPTBot and still allow OAI-SearchBot.
Should I block AI crawlers from my website?
Block training crawlers only if you object to your content training AI models or they put real strain on your server. Keep AI search crawlers open if you want customers to find your brand in ChatGPT, Perplexity or Claude.
How do I stop AI bots from slowing down my website?
Block cart, checkout, filter and internal search URLs for all bots, then rate limit any crawler that sends too many requests. Caching your public pages also cuts the load each bot visit creates.
Do AI bots respect robots.txt?
Major crawlers from Google, OpenAI and Anthropic say they follow robots.txt for automatic crawling. User-triggered fetchers like ChatGPT-User may not, since a person starts the request. Some scrapers ignore it completely, which is why firewall rules matter.
Does blocking Google-Extended remove me from AI Overviews?
No. AI Overviews and AI Mode use Googlebot's index. Google-Extended only controls whether Google uses your content for Gemini training.
How do I know which AI bots are crawling my site?
Check your server access logs for user-agent names like GPTBot, ClaudeBot or PerplexityBot, or open your CDN's bot analytics. Verify suspicious visitors against each company's published IP ranges.
Can I allow AI search but block AI training?
Yes. Allow OAI-SearchBot, Claude-SearchBot and PerplexityBot, then disallow GPTBot, ClaudeBot, CCBot and Google-Extended in robots.txt. Each bot reads its own rules.